AI Search or Model Training: What Does Your Business Gain?
Written by Evren BalPublished · 6 min read
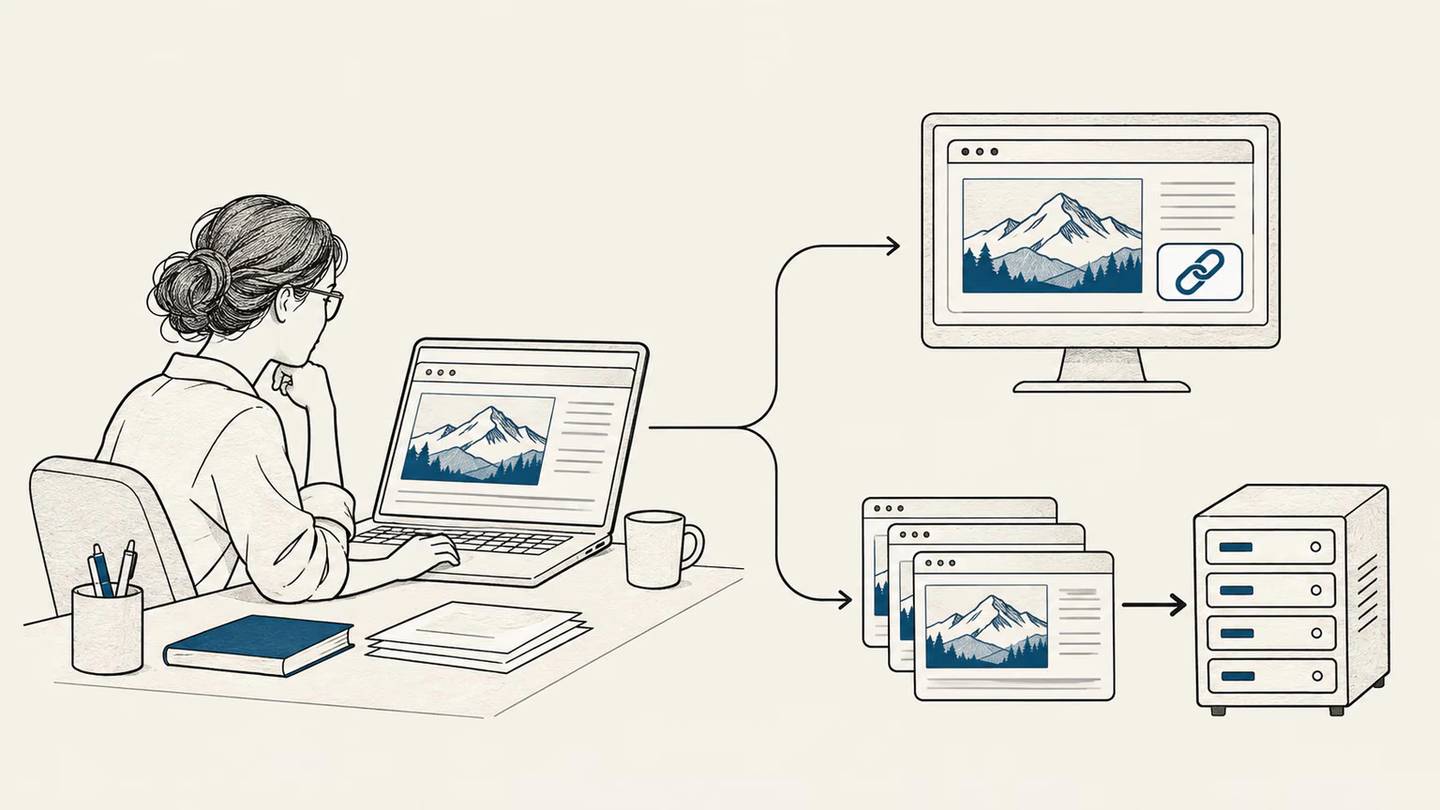
A company publishes an explainer because it wants to reach people. A manufacturer publishes product information because it wants people to understand the product and find its technical documentation. Both invest in content, but they expect different things from it.
I thought about that distinction when OpenAI announced support for a shared way for websites to express AI training preferences. The signal would be expressed through robots.txt, which site owners use to communicate with automated crawlers. OpenAI said it aimed to implement the signal in the coming months; the announcement does not establish that the signal is active yet.
The announcement raised a broader question for me: What is the difference between having your content found in AI search and having it used to train a model? What does your business gain from each?
Search finds a source; training changes a model
When answering a question, an AI system may search the web, retrieve a page and use it to support its response. It may also link to that page. A system may still choose not to cite an accessible page, but access gives it a chance to surface the source and send readers to the site.
Training is a different process. A provider may use collected text to develop a model. The model learns patterns from many examples, including how words and ideas relate to each other. When it answers a later question, it need not identify the page from which it learned something or name its publisher. Allowing training access does not guarantee that a page will be included either.
A user can also provide a link and ask an AI system to examine that specific page. This is a separate route from automated search and training. OpenAI describes a different agent for user-initiated visits and says robots.txt rules may not apply to those requests.
OpenAI's crawler documentation sets out separate controls for GPTBot, which gathers content that may be used for training, and OAI-SearchBot, which supports ChatGPT search. Under OpenAI's documented approach, a site can block the training crawler while allowing the search crawler. Other providers do not necessarily offer the same separation.
What does a clinic expect from an explainer?
Imagine a clinic publishes a page answering common questions about rhinoplasty. The page also invites readers to contact the clinic when appropriate.
The clinic may have invested staff time and expertise in the page. It may hope that readers find it, become familiar with the practice and get in touch if they need help. A citation in AI search could start that journey. But not every citation leads to a visit, and not every visitor becomes a patient.
If the page is included in training, a model may later answer a general question about rhinoplasty without mentioning the clinic. The invitation to contact it may never reach the user. That does not prove a particular answer was learned from that clinic or that the clinic lost a patient. It shows why search visibility and training use can benefit a business in different ways.
General health information can also have public value. A provider may welcome its contribution to a wider body of knowledge. Whether that contribution measurably benefits the clinic's brand is a separate question.
Product information has a different job
Now consider a building materials manufacturer. Its product page names a particular product and describes suitable surfaces, application conditions and technical documentation.
Here, the brand and product are central to the information. The company may want a professional to match the product to the right need and find the current technical sheet. Training on product information could help a model answer questions about the product. It does not guarantee that the model will name it correctly, reproduce every technical detail or link to the source.
Product information also changes. A formula, application limit or technical sheet can be updated, and we cannot assume a previously trained model will reflect that change immediately. Making the current product page discoverable and directing readers to the manufacturer's documentation can therefore serve a different purpose from inclusion in training.
Even then, appearing in AI search does not mean a sale. A correct product mention, a technical-sheet visit, a quote request and a purchase are separate outcomes.
Can a publisher require attribution?
A content owner can state an attribution preference or set out terms of use on a page. That makes the expectation visible. It does not ensure that every AI provider will read it and apply it to every relevant answer.
The IETF draft for the shared training signal focuses on expressing a training preference. The draft I reviewed does not define a rule that makes a model link to the owner in every relevant answer. It is also an Internet-Draft, not a completed standard.
Attributing a work used in training is a different problem from linking to a page consulted for a particular answer. Creative Commons' discussion of attribution makes that distinction. The legal effect of a licence or usage condition depends on how content is used and the applicable law.
Providers do not all use the same controls
The distinction between training and search is useful, but each provider offers different controls.
For example, Google says its Google-Extended control affects training future Gemini models and the use of search content to ground responses in specified Gemini products. Google says this control does not affect inclusion or ranking in Google Search.
This matters in practice: a company that limits training use may also prevent some products from using its current content to support answers. Before setting a preference, it needs to understand which provider, product and use the control covers.
Start with the job each page does
A company may not expect the same result from every page. An explainer may be there to reach the right audience. A product page may help someone make a technical decision. An original research report may be intended to earn recognition for the organisation's findings.
Before changing a technical setting, I would ask:
- What business outcome or reader need does this page serve?
- Is the information general, or specific to a brand, product or original study?
- How important are a brand mention and a source link in an AI answer?
- What could happen if the information is outdated or incomplete?
- Does the provider actually let us manage training and search preferences separately?
The right settings will depend on the page and the business goal. A publisher may value wider use of its knowledge. Another company may see no measurable return from unattributed use. A manufacturer may want its product to be discoverable while placing greater weight on accuracy and currency.
OpenAI's announcement brought this question into focus for me. A preference in robots.txt looks like a technical setting, but behind it are decisions about content investment, distribution and control. To judge which use is valuable, first understand what the content is meant to do for the business and its readers.
If this article was useful
Linking to it from a relevant page on your website or sharing it on social media genuinely helps it reach more people. Thank you for your support.
Linking and brand guidelines →About this article
- Use of artificial intelligence
- AI-assisted — Evren Bal defined the idea and direction of this article. AI tools assisted with research, drafting and translation.
A small experiment
Loading personal metrics…